 Jesse Jacoby
The COO of a specialty manufacturer showed me a pricing analysis his team had built in a single afternoon. The same work used to take his analysts three weeks. It was forty pages long, cleanly sourced, internally consistent, and it recommended a six percent price increase across a customer segment that had been slowly eroding for two years.
It was also answering the wrong question. The segment was not leaving over price. It was leaving because on-time delivery had slipped below eighty percent, and two of the largest accounts had said so directly to their sales rep. Nobody asked what was actually driving the erosion before the analysis started, and nobody in the review meeting asked what would have to be true for the recommendation to be right. The model did exactly what it was told. The team came within one steering committee of raising prices on customers who were already halfway out the door.
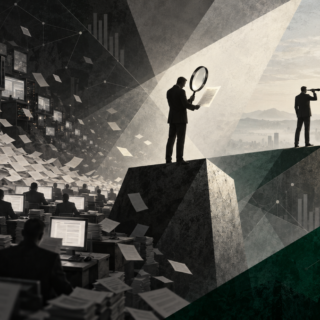
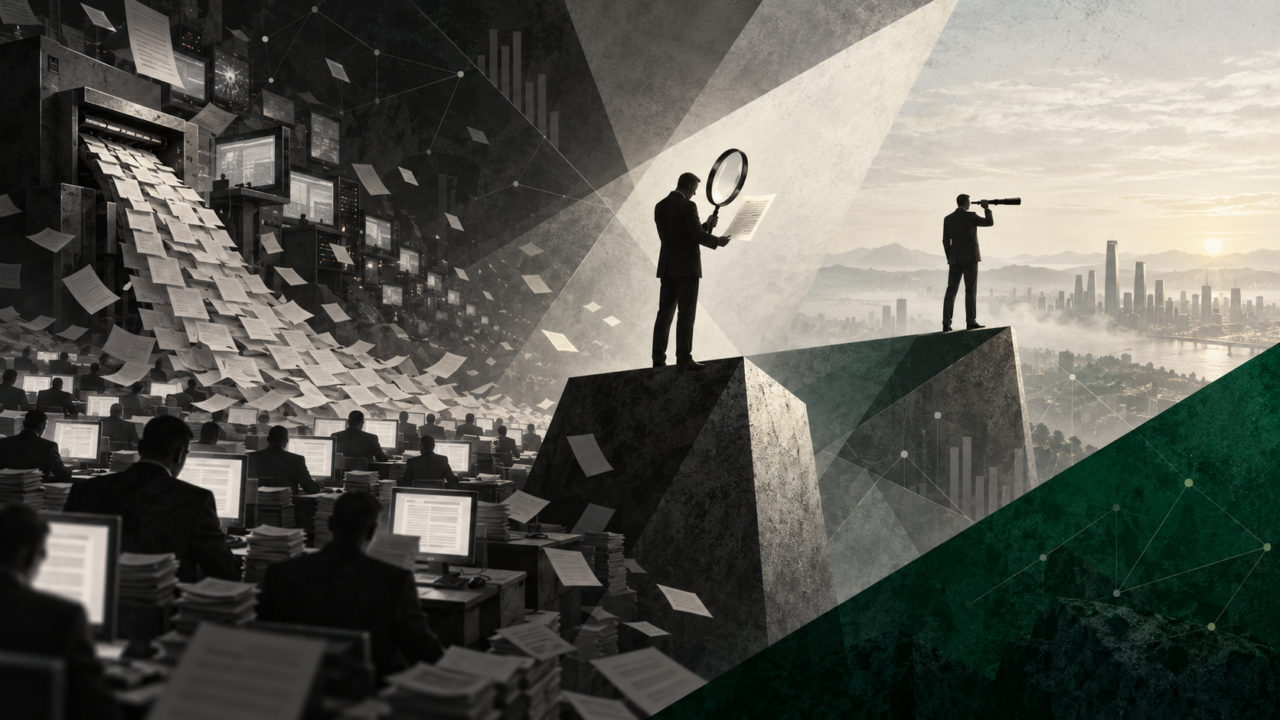
That afternoon captures the shift most organizations have not caught up with. When output becomes cheap, the scarce skill moves to the edges of the work: framing the right problem before the model runs, and pressure-testing the answer after it comes back. I call the value of those two edges the judgment premium, and it is rising faster than almost anyone is investing in it.
Cheap Answers Move the Bottleneck
Every time a technology makes something abundant, value migrates to whatever that abundant thing depends on. Cheap printing made editors more valuable, not less. Cheap data made the people who knew which numbers mattered more valuable than the people who could pull them.
Generative AI is doing the same thing to analysis, drafting, and synthesis. A competent first answer now costs close to nothing. That does not make answers worthless. It makes the quality of the question, and the rigor applied to the answer, the part that determines whether any of it is worth acting on.
Most enterprises have spent the last two years investing in the middle. Licenses, platforms, copilots, prompt libraries, and tool training. BCG’s 2025 AI at Work survey of more than 10,000 employees found that only about a third say they have been properly trained on AI, and most of that training is about how to operate the tools.1 Almost nothing has been spent on the layer that decides whether the output deserves to be trusted.
The Frontier Is Jagged, and Nobody Hands You the Map
The best evidence on this comes from a field experiment with 758 BCG consultants run by researchers from Harvard, Wharton, MIT, and Warwick. On tasks well suited to AI, consultants using it finished 12.2 percent more tasks, worked 25.1 percent faster, and produced work rated more than 40 percent higher in quality. On a task that looked similar but sat just outside what the model could do well, consultants using AI were 19 percentage points less likely to reach the correct answer than those working without it.2
The researchers called this the jagged technological frontier. The line between what AI does brilliantly and what it does confidently and wrong is irregular, and it does not announce itself. The output on the wrong side of the line looks just as polished as the output on the right side.
That is the heart of the judgment premium. The tool cannot tell you which side of the frontier your task sits on. A person has to make that call, every time, and the cost of getting it wrong grows with the speed and fluency of the tool.
Confidence Is Quietly Replacing Scrutiny
A 2025 study by Microsoft Research and Carnegie Mellon surveyed 319 knowledge workers across 936 real examples of AI use at work. The pattern was clear. The more confidence people had in the AI’s ability to handle a task, the less critical thinking they reported applying to it. The more confidence they had in their own ability, the more scrutiny they applied.3
The same study found that critical thinking does not disappear when AI enters the workflow. It changes shape. It shifts from gathering information to verifying it, from producing content to integrating it, and from doing the task to stewarding it.
That is a job redesign. Most organizations have not written it down, trained for it, or measured it. They handed people a faster engine and assumed the steering would take care of itself.
The Two Edges of the Work
The judgment premium sits in two specific places, and it helps to name them precisely.
Framing comes before the model runs. What decision are we actually trying to make? What would change our mind? What is out of scope, and why? Which constraints are real and which are habits? A well-framed problem handed to an average analyst beats a poorly framed problem handed to the best model available. Framing is also where most leadership teams spend the least time, because it feels slow and produces nothing visible.
Pressure-testing comes after the answer arrives. What would have to be true for this to be right? Where is it most likely to be wrong? What did it leave out? Who in the organization would disagree, and what do they know that the model does not? This is the discipline of treating a fluent answer as a hypothesis rather than a conclusion.
Everything in the middle is increasingly automated. The edges are not, and they will not be anytime soon, because they depend on context, accountability, and consequences that live inside your organization rather than inside the model.
Where to Build It Deliberately
Judgment does not develop by accident, and it does not develop from tool training. Five moves I recommend to leadership teams:
Require a framing step before consequential analysis. A one-page problem statement, agreed by the decision owner, before anyone opens a tool. It names the decision, the options on the table, and the evidence that would change the call. It takes an hour and saves weeks.
Name a challenger for decisions that matter. For any AI-assisted recommendation above a set threshold, assign one person whose explicit job is to find the flaw. Rotate the role so it builds capability across the team rather than creating a permanent skeptic.
Rebalance the learning budget. If ninety percent of your AI enablement spend is tool fluency, shift a meaningful share toward problem framing, assumption testing, and decision review. Those skills compound. Tool skills depreciate with every product release.
Protect the developmental reps. Judgment is built by making calls and seeing the results. As AI absorbs the entry-level work where people used to practice, leaders have to create deliberate opportunities for emerging talent to frame problems and defend recommendations under real scrutiny.
Reward the calls people stopped. Most performance systems celebrate what shipped. Start recognizing the analysis that was questioned, the recommendation that was killed, and the assumption someone caught before it reached the board.
Measure the Calls, Not the Volume
The metrics most organizations use to track AI adoption measure activity: usage rates, prompts submitted, hours saved, documents produced. Every one of them rewards more output, and none of them tells you whether the output improved a decision.
Add a small set of judgment measures alongside them. How often are major decisions revisited within six months? How many recommendations were changed or stopped during review? Can your teams name the assumptions behind their last three significant calls? These are harder to collect, which is exactly why they are worth collecting.
The Premium Is Already Being Paid
The COO did not ban the tool. He added a thirty-minute framing conversation to the front of every pricing and portfolio analysis, and he asked his most skeptical regional director to sit in on the reviews with a standing mandate to break the recommendation. The next analysis still took an afternoon. It started from a different question, and it pointed the team at delivery performance instead of price.
AI has not reduced the need for judgment. It has concentrated it. The organizations that pull ahead will not be the ones with the most licenses or the fastest output. They will be the ones that got serious about the calls the model cannot make.
So look at where your AI investment went this year. How much of it went into the middle of the work, and how much into the edges where the value is actually decided?
References
- Boston Consulting Group, “AI at Work 2025: Momentum Builds, but Gaps Remain,” 2025. A survey of more than 10,600 leaders, managers, and frontline employees across 11 countries and regions found that only about one third of employees say they have been properly trained on AI, and that adoption rises sharply with more substantial training and visible leadership support.
- Fabrizio Dell’Acqua, Edward McFowland III, Ethan Mollick, Hila Lifshitz-Assaf, Katherine Kellogg, Saran Rajendran, Lisa Krayer, François Candelon, and Karim Lakhani, “Navigating the Jagged Technological Frontier: Field Experimental Evidence of the Effects of AI on Knowledge Worker Productivity and Quality,” Harvard Business School Working Paper 24-013, 2023. In a field experiment with 758 BCG consultants, AI users completed 12.2 percent more tasks, 25.1 percent faster, with more than 40 percent higher quality on tasks within the AI frontier, but were 19 percentage points less likely to produce correct solutions on a task outside it.
- Hao-Ping (Hank) Lee, Advait Sarkar, Lev Tankelevitch, Ian Drosos, Sean Rintel, Richard Banks, and Nicholas Wilson, “The Impact of Generative AI on Critical Thinking: Self-Reported Reductions in Cognitive Effort and Confidence Effects From a Survey of Knowledge Workers,” Proceedings of the 2025 CHI Conference on Human Factors in Computing Systems. A survey of 319 knowledge workers covering 936 examples found that higher confidence in AI was associated with less critical thinking, while higher self-confidence was associated with more, and that AI shifts critical thinking toward verification, integration, and task stewardship.